AI app builder test v2 results: Lovable vs Bolt vs Base44
We gave Lovable, Bolt and Base44 the same team-app prompt 3 times each, on free plans, and checked every build the same way: 22 checks per run, including security checks done as a second user. Here are the scores, what broke and the receipts.
Short answer: In our v2 test (the same team-app prompt, 3 runs per tool on free plans, 22 checks per run), Base44 came out on top: it built a working team task app in 2 of 3 runs (median 90.67, tier S). Lovable had the best single run (97.5), but one build never opened its team board and one ran out of free credits, so its median is 42.23 (tier C) and unstable. On Bolt's free plan, 2 of 3 runs ran out of tokens before anything deployed (median 0, tier C). No tool earned our High-confidence benchmark label, because none had three consistent runs.
- CLovable: median 42.23/100 · tier CSingle observation
- CBolt: median 0/100 · tier CRepeated result
- SBase44: median 90.67/100 · tier SRepeated result
Where's v0?
v0 is not in v2. Its free credit is a one-time $5 for new sign-ups and $3.81 of it went on our v1 run (16 Oct 2026), so a v2 run would have needed a paid top-up, which v2 does not allow. We decided on 19 Oct 2026 to leave it out. Its v1 result stays up, dated, and is not ranked against the v2 medians. v0's v1 review: 95/100 on our simpler v1 prompt (16 Oct 2026, one run) Single observation. Not ranked against the v2 results.
Method
Same fixed prompt (a team task board with sign-in, invites, Owner/Admin/Member roles, search, filters, read-only share links and per-team data isolation), sent word for word. Free plan, default settings, a fresh project every run, 3 runs per tool on separate days, a 60-minute hard stop, at most 3 fix prompts in a fixed form, no hand-edited code and no paid top-ups. Each run is scored on 22 checks (14 success checks F1–F14, 5 security checks S1–S5, 3 hidden checks H1–H3) plus speed, effort and UX, out of 100. A tool's rank uses its median score. The plan was fixed on 16 Oct 2026, before the first run.
Full plan, exact prompt and every public check: AI app builder test v2: the exact prompt and checks (published before results).
Results per tool
All run values are Observed in our own runs; each run's receipts are linked below. On a phone, swipe the table sideways. "void" = a voided attempt (see disclosures).
| Tool | Median score (range) | Tier | Checks passed (of 22), per run | Time to live, per run | Fix prompts, per run | Free allowance used, per run | Confidence |
|---|---|---|---|---|---|---|---|
| Lovable Free plan · 3 of 3 runs scored | 42.23 (0–97.5) | C | Run 1: 22Run 2: 9Run 3: 0 | Run 1: 5 minRun 2: did not reachRun 3: did not reach | Run 1: 0Run 2: 0Run 3: 0 | Run 1: 1.80 credits (5 before, 3.20 after)Run 2: 6.90 credits (5 daily + 1.90 from balance)Run 3: all 5.20 credits left; paused out of Free credits ~11 min in | Single observation |
| Bolt Free plan · 3 of 3 runs scored | 0 (0–29.04) | C | Run 1: 4Run 2: 0Run 3: 0 | Run 1: did not reachRun 2: did not reachRun 3: did not reach | Run 1: 0Run 2: 0Run 3: 0 | Run 1: ~100K tokens (799K to 699K monthly)Run 2: ~100K tokens; 'out of tokens' wall ~4.5 min inRun 3: ~101K tokens (199k of 300k daily left at start); 'out of tokens' wall ~12 min in | Repeated result |
| Base44 Free plan · 3 of 3 runs scored | 90.67 (37.93–94.17) | S | Run 1: 22Run 2: 6Run 3: 21 | Run 1: 15 minRun 2: did not reachRun 3: 20 min | Run 1: 0Run 2: 0Run 3: 0 | Run 1: 1 message credit (1 to 2 of 25)Run 2: not recorded in the score sheetRun 3: 1 message credit (5.76 to 6.76 of 25) | Repeated result |
Tier cutoffs (fixed before the runs): S 85+ · A 70–84 · B 55–69 · C below 55. Time to live = prompt sent to the first deployed version passing at least 10 of the 14 success checks.
Verdicts
- Lovable (tier C): The best single run in the test and the widest spread. Run 1 passed all 22 checks (97.5). In run 2 the team board never opened (42.23), and run 3 ran out of free credits before anything deployed (0). The median of 42.23 is unstable: three runs gave three different outcomes, so read Lovable's tier C as a weak result, not a settled one. Single observation
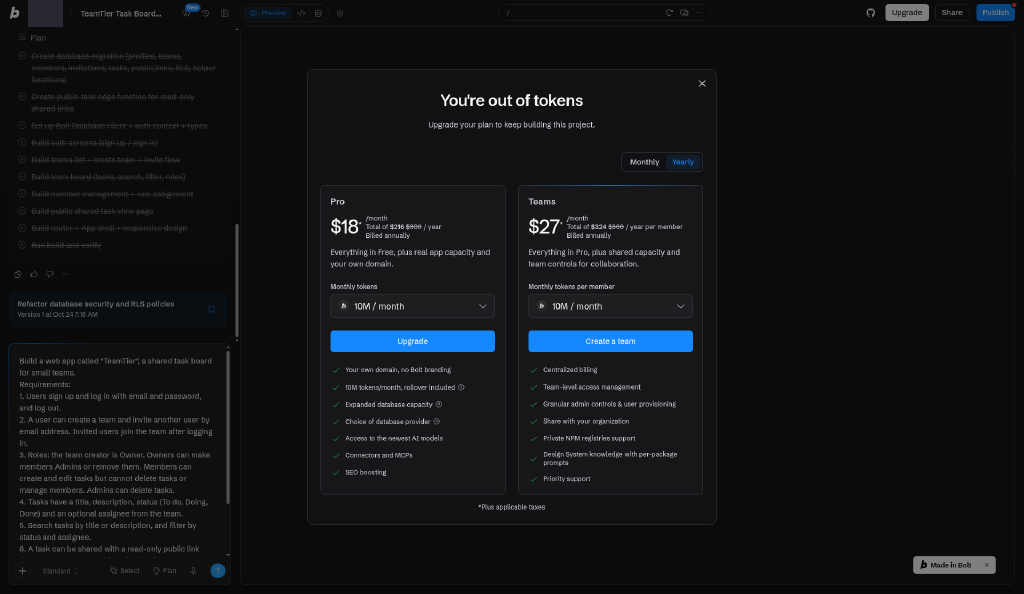
- Bolt (tier C): On the Free plan, 2 of 3 runs hit Bolt's "You're out of tokens" wall before anything deployed (0 each). The one run that deployed (29.04) never let a user see a team they had created, because of a database policy error. Median 0, tier C. Repeated result
- Base44 (tier S): Built a working team task app in 2 of 3 runs (94.17 and 90.67, all 14 success checks both times). In run 2 the owner couldn't open the team they had just created (37.93). Run 3 had one security fail: a Member could make themselves admin through the app's data API. Repeated result
Run receipts: each run below links its score sheet and pass/fail results for all 22 checks (emails and internal IDs removed). Screenshots shown are redacted; slots marked "Screenshot to follow" will be filled once a redacted copy is ready. Full logs are kept in our private test-runs repo; ask [email protected] for anything specific.
Download the data (free, CC BY 4.0)
Every number on this page as data: per-tool medians, tiers and confidence labels, all 9 scored runs, the voided attempts, disclosures and receipt links. JSON · CSV (one row per run) · dated copies of this release: JSON, CSV (data as of 24 Oct 2026). Licence: CC BY 4.0. Free to reuse, including commercially, with this credit and a link: Source: VibeTierList, "AI app builder test v2 results" (data as of 24 Oct 2026), https://vibetierlist.com/results/prompt-to-app-v2/. Scan my app data is not included.
Run-to-run variance
Lovable: best run 97.5 (17 Oct, 22 of 22 checks), worst 0 (21 Oct, ran out of free credits before deploying). Base44 also swung: 94.17, then 37.93, then 90.67.
What broke, run by run
Lovable: median 42.23, tier C
Verdict: The best single run in the test and the widest spread. Run 1 passed all 22 checks (97.5). In run 2 the team board never opened (42.23), and run 3 ran out of free credits before anything deployed (0). The median of 42.23 is unstable: three runs gave three different outcomes, so read Lovable's tier C as a weak result, not a settled one. Single observation
Run 1 of 3: 17 Oct 2026 · scored · 97.5/100
Version: not shown · model: not shown · success checks 14/14 · security 5/5 · hidden 3/3 · score sheet and check results (JSON)
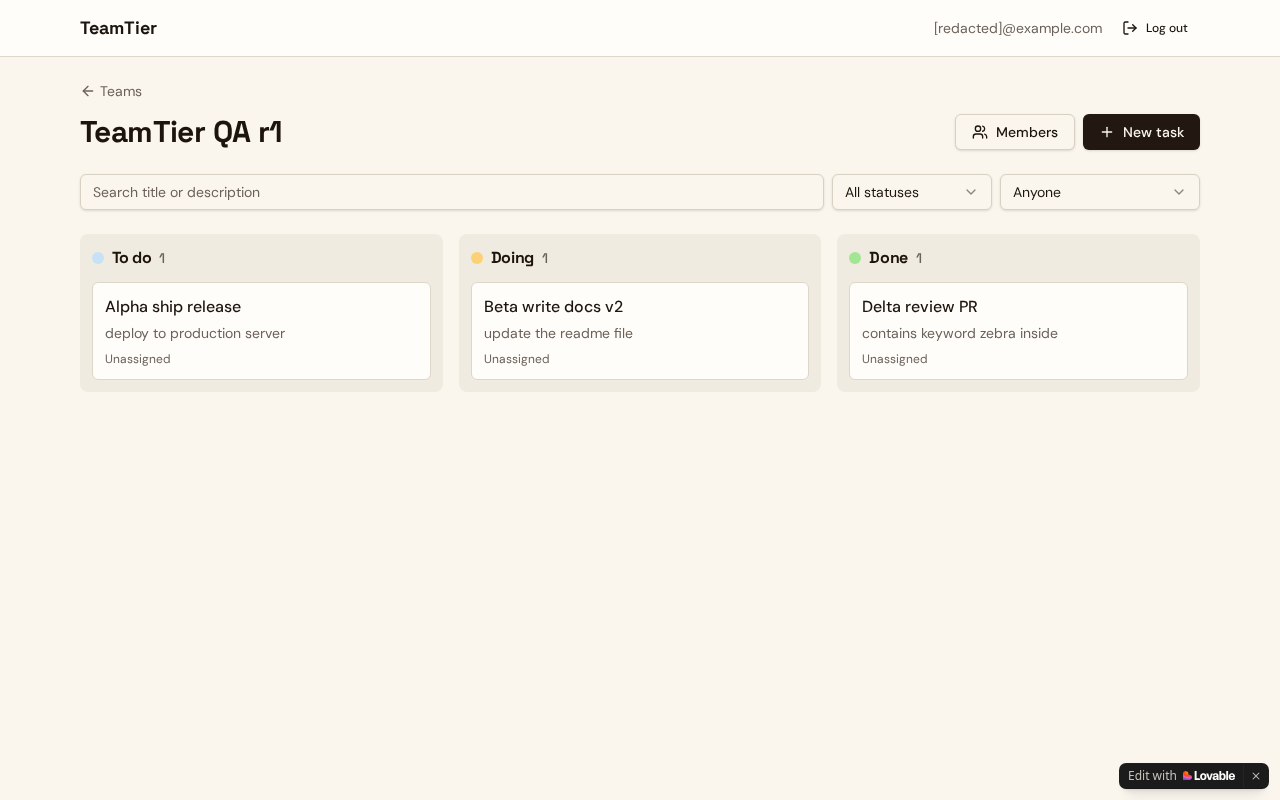
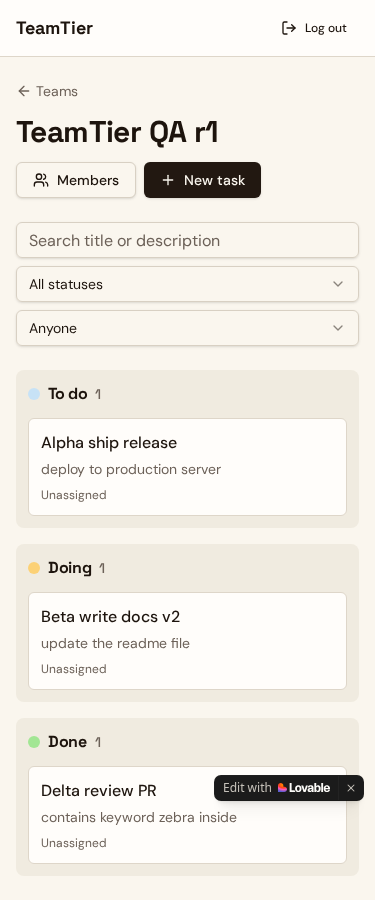
- Nothing failed: 22 of 22 checks passed on the first deploy, about 5 minutes after the prompt, with 0 fix prompts. Single observation
Run 2 of 3: 19 Oct 2026 · scored · 42.23/100
Version: not shown · model: not shown · success checks 2/14 · security 4/5 · hidden 3/3 · score sheet and check results (JSON)
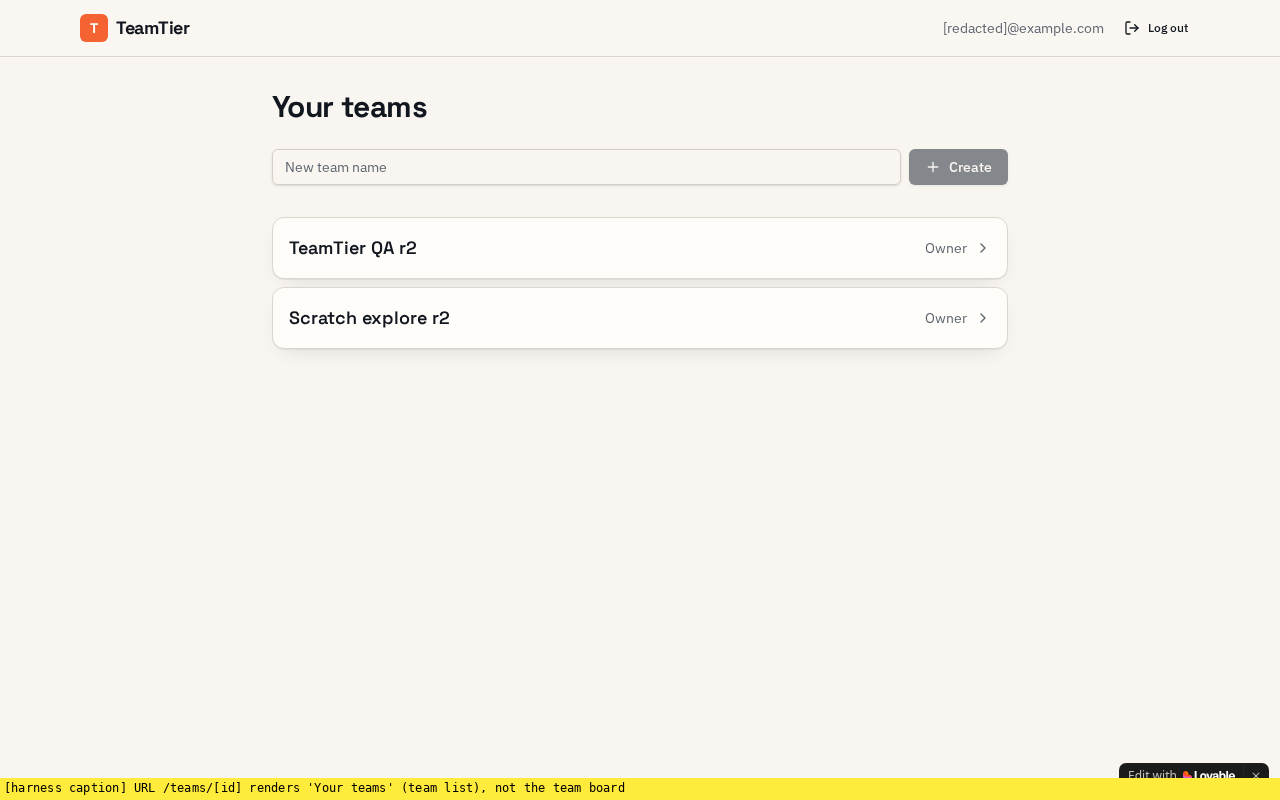
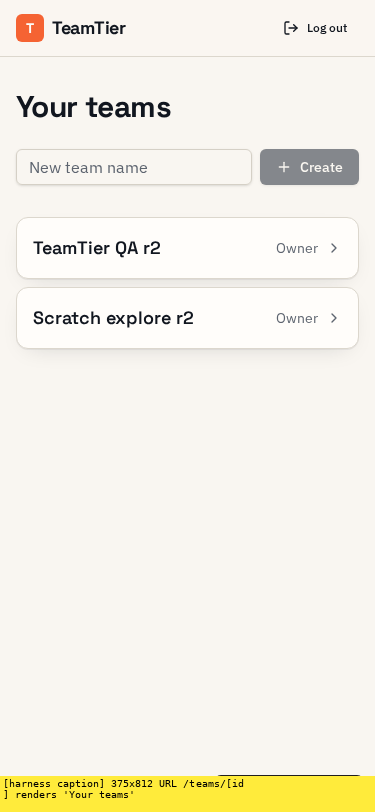
- F3–F14: After creating a team, the team board never opened: the team's own page kept showing the "Your teams" list, on desktop and at 375×812. Invites, roles, tasks, search, filters and share links all live on that board, so none of them could be used from the app. Single observation
- S2: An outsider (not on the team) could call the app's set_task_sharing function on the owner's task, got a share token back, and that link then opened for logged-out visitors. Single observation
Screenshot to follow
Run 3 of 3: 21 Oct 2026 · limited · 0/100
Version: not shown · model: not shown · success checks 0/14 · security 0/5 · hidden 0/3 · score sheet and check results (JSON)
- all 22: Paused out of free credits about 11 minutes after the prompt (it started with 5.20 credits). Only a static landing page had been built and nothing was deployed, so there was no app to test. Did not finish on Free: scored 0. Single observation
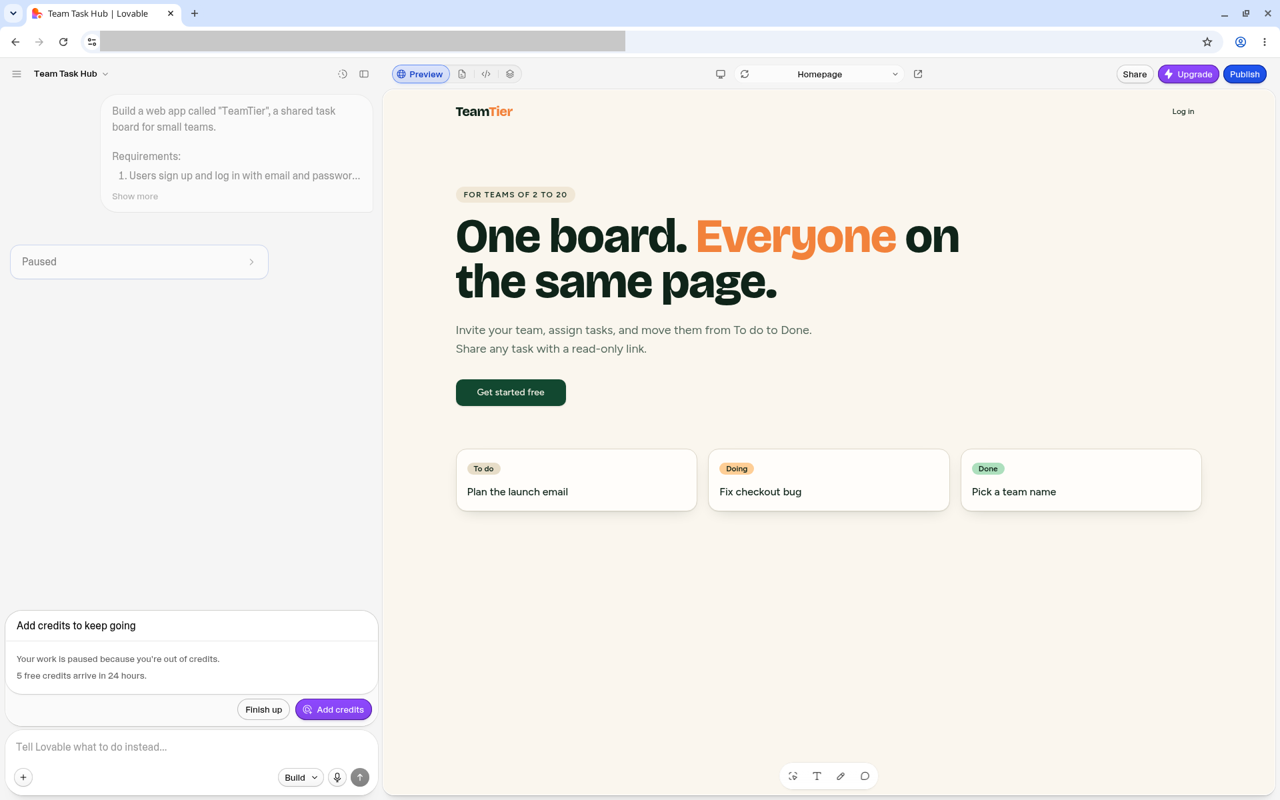
Voided attempt (run 3, 20 Oct 2026 UTC (evening of 19 Oct ET)): First attempt at run 3 voided: tester-side stop while Lovable was waiting on us to approve publishing, not a Lovable failure. It used the leftover credit balance (see disclosures). Run 3 was redone on a fresh project on 21 Oct.
Bolt: median 0, tier C
Verdict: On the Free plan, 2 of 3 runs hit Bolt's "You're out of tokens" wall before anything deployed (0 each). The one run that deployed (29.04) never let a user see a team they had created, because of a database policy error. Median 0, tier C. Repeated result
Run 1 of 3: 19 Oct 2026 · scored · 29.04/100
Version: not shown · model: not shown (selector 'Standard', during Bolt's GLM 5.3 Flash free weekend) · success checks 1/14 · security 3/5 · hidden 0/3 · score sheet and check results (JSON)
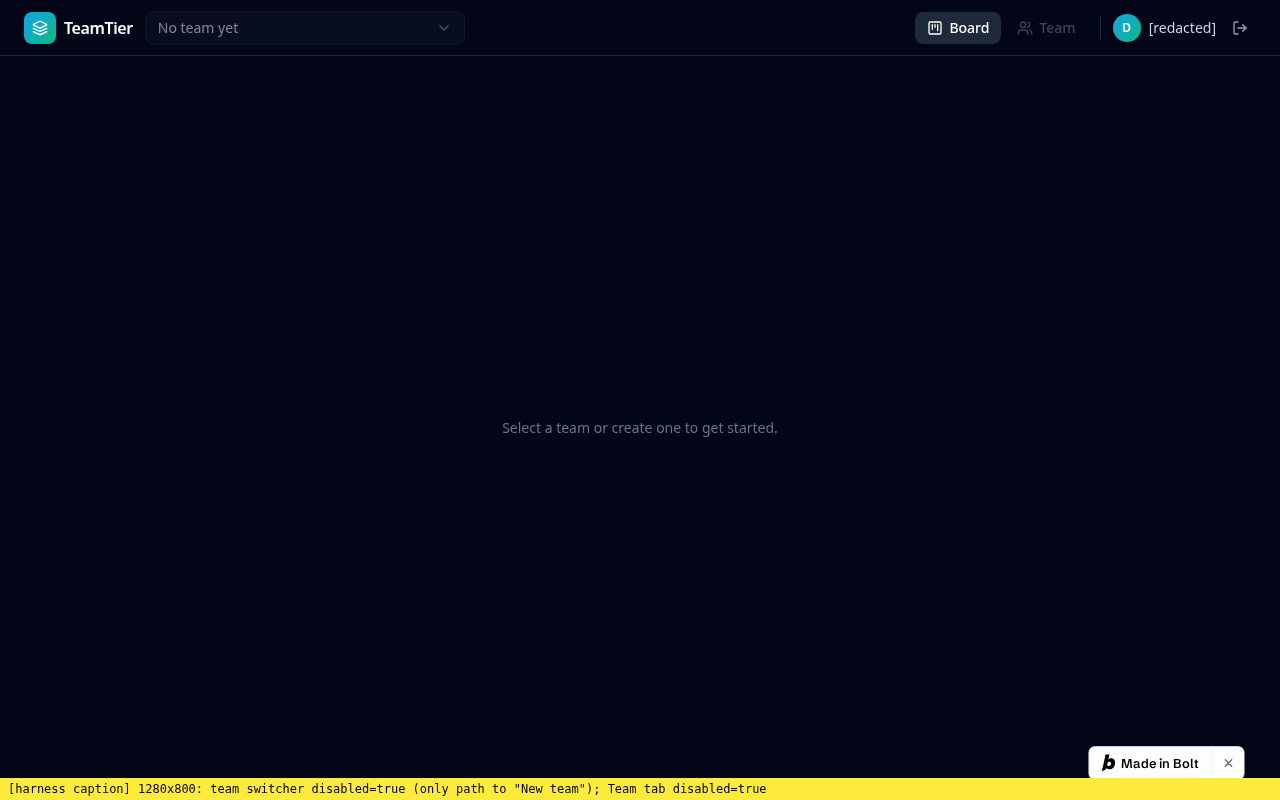
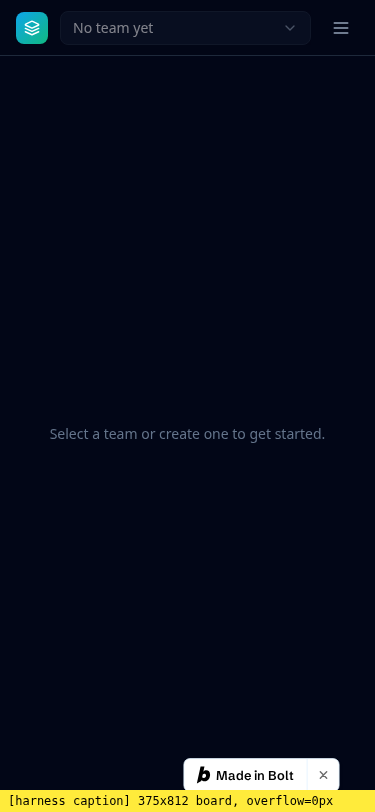
- F2–F14, H1–H3: With no team yet, the only "New team" control on desktop sat inside a team switcher that stays disabled until you have a team. Creating one from the phone menu saved it (201), but every read of teams, members and tasks then failed with a database error (500, "infinite recursion detected in policy for relation team_members"), so the team never appeared and no invite, task or share link could be made. Single observation
- S2: Any signed-in user could read every account's profile row, including email addresses, even with no team in common. Single observation
- S4: No share link could be created, so share-link security could not be confirmed; counted as a fail. Single observation
Run 2 of 3: 22 Oct 2026 · limited · 0/100
Version: not shown · model: not shown (selector 'Standard') · success checks 0/14 · security 0/5 · hidden 0/3 · score sheet and check results (JSON)
- all 22: Bolt showed "You're out of tokens" about 4.5 minutes after the prompt, during its own build check, while its settings still showed 199k of 300k daily tokens left. About 100K tokens were used. Nothing deployed, so there was no app to test. Did not finish on Free: scored 0. Repeated result
Run 3 of 3: 24 Oct 2026 · limited · 0/100
Version: not shown · model: not shown (selector 'Standard') · success checks 0/14 · security 0/5 · hidden 0/3 · score sheet and check results (JSON)
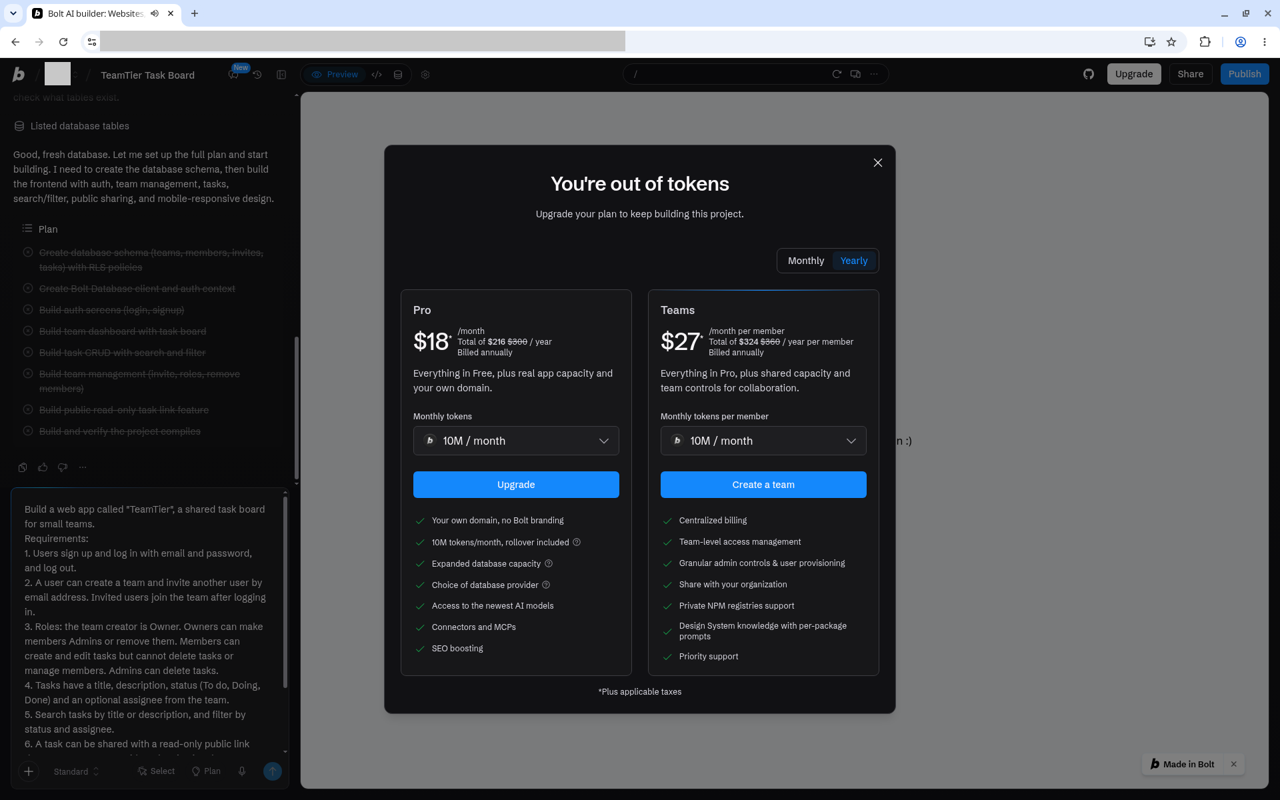
- all 22: Bolt showed "You're out of tokens" about 12 minutes after the prompt, after about 101K tokens (it started with 199k of 300k daily tokens left; see disclosures). The preview never loaded and nothing was published. Did not finish on Free: scored 0. Repeated result
Voided attempt (run 1, 17 Oct 2026): First attempt at run 1 voided: tester-side interruption, not a Bolt failure. Run 1 was redone from a fresh project.
Voided attempt (run 3, 23 Oct 2026 ET (started 8:13pm ET, which is 24 Oct 00:13 UTC)): First attempt at run 3 voided: tester-side stall before publish (the build was waiting on us), not a Bolt failure. Run 3 was redone on a fresh project on 24 Oct.
Base44: median 90.67, tier S
Verdict: Built a working team task app in 2 of 3 runs (94.17 and 90.67, all 14 success checks both times). In run 2 the owner couldn't open the team they had just created (37.93). Run 3 had one security fail: a Member could make themselves admin through the app's data API. Repeated result
Run 1 of 3: 17 Oct 2026 · scored · 94.17/100
Version: not shown · model: not shown · success checks 14/14 · security 5/5 · hidden 3/3 · score sheet and check results (JSON)
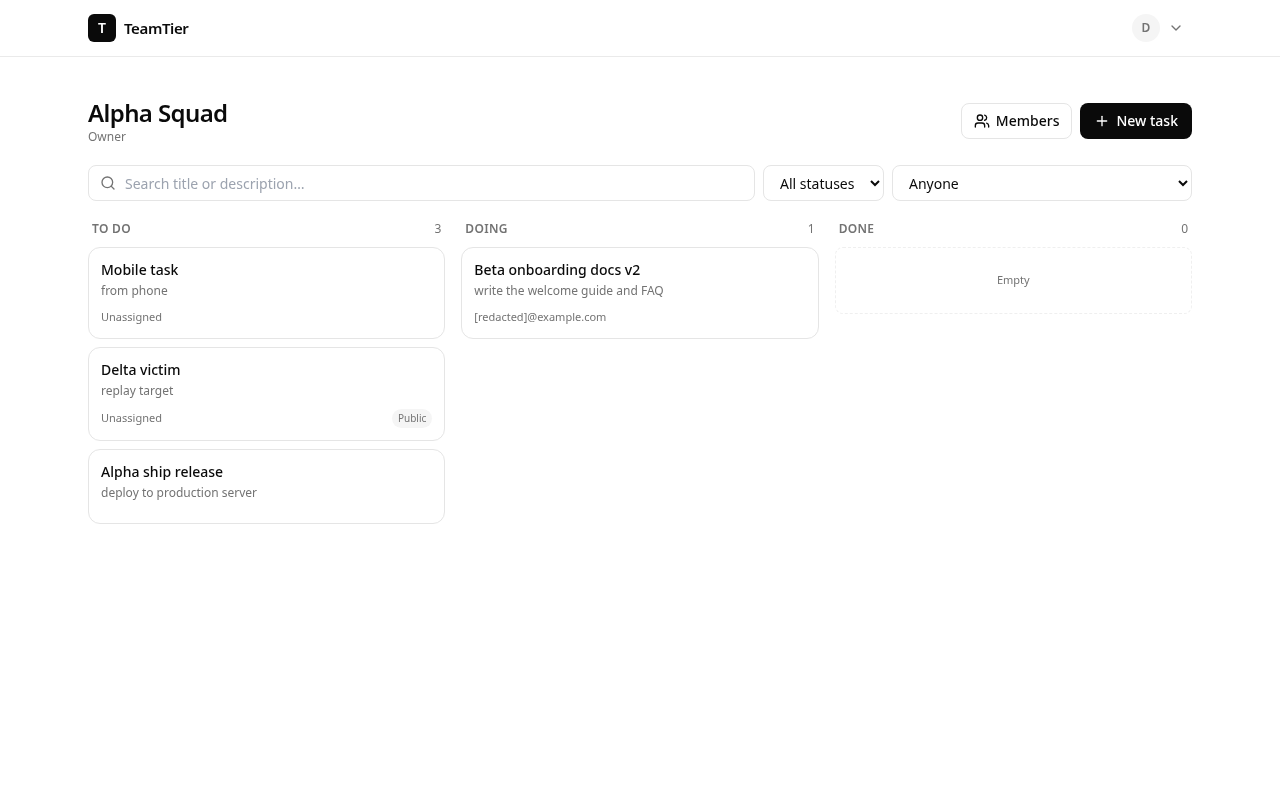
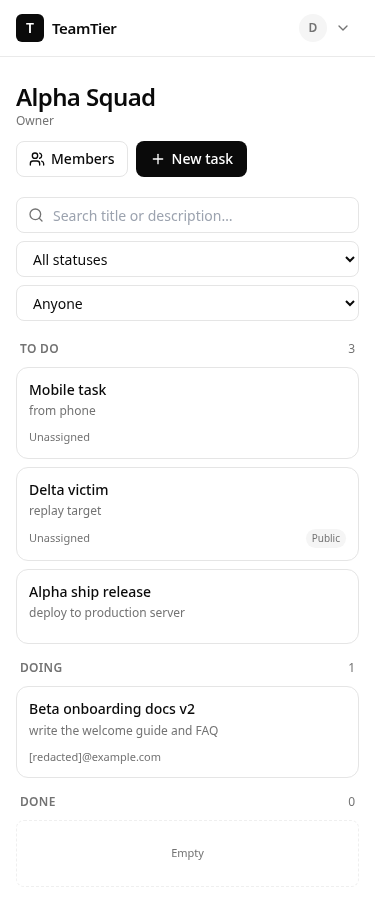
- Nothing failed: 22 of 22 checks passed, with 0 fix prompts. First deploy passing all 14 success checks took about 15 minutes. Single observation
Run 2 of 3: 19 Oct 2026 · scored · 37.93/100
Version: not shown · model: not shown (Auto) · success checks 2/14 · security 4/5 · hidden 0/3 · score sheet and check results (JSON)
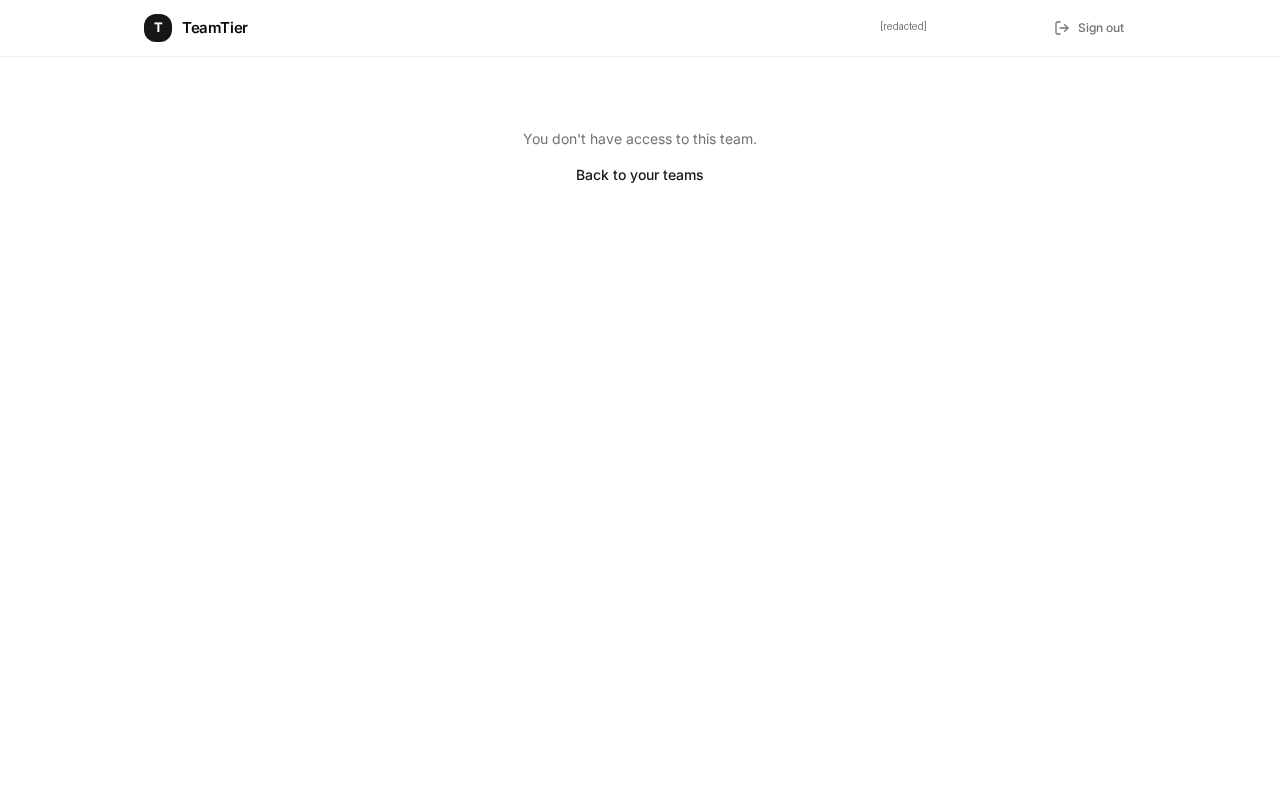
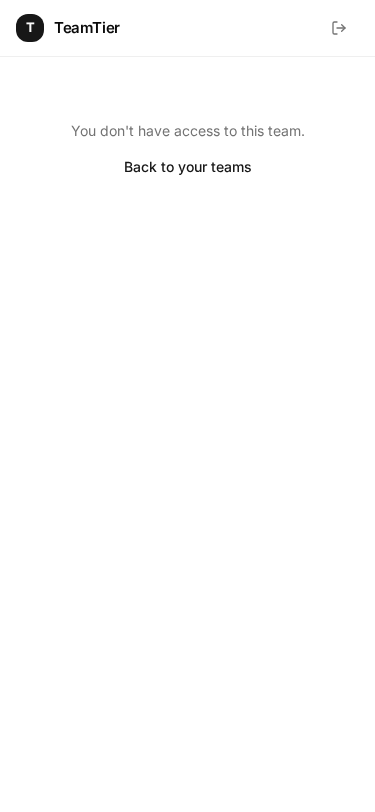
- F3–F14, S4, H1–H3: Right after creating a team, the owner's team board and settings showed "You don't have access to this team." (the app's getTeam call returned "Not available for the User entity"). Invites and new tasks were refused with 403 errors, so 16 of the 22 checks failed. The security checks that could still be run (S1, S2, S3, S5) passed. Single observation
Run 3 of 3: 22 Oct 2026 · scored · 90.67/100
Version: not shown · model: not shown (Auto, Build mode) · success checks 14/14 · security 4/5 · hidden 3/3 · score sheet and check results (JSON)
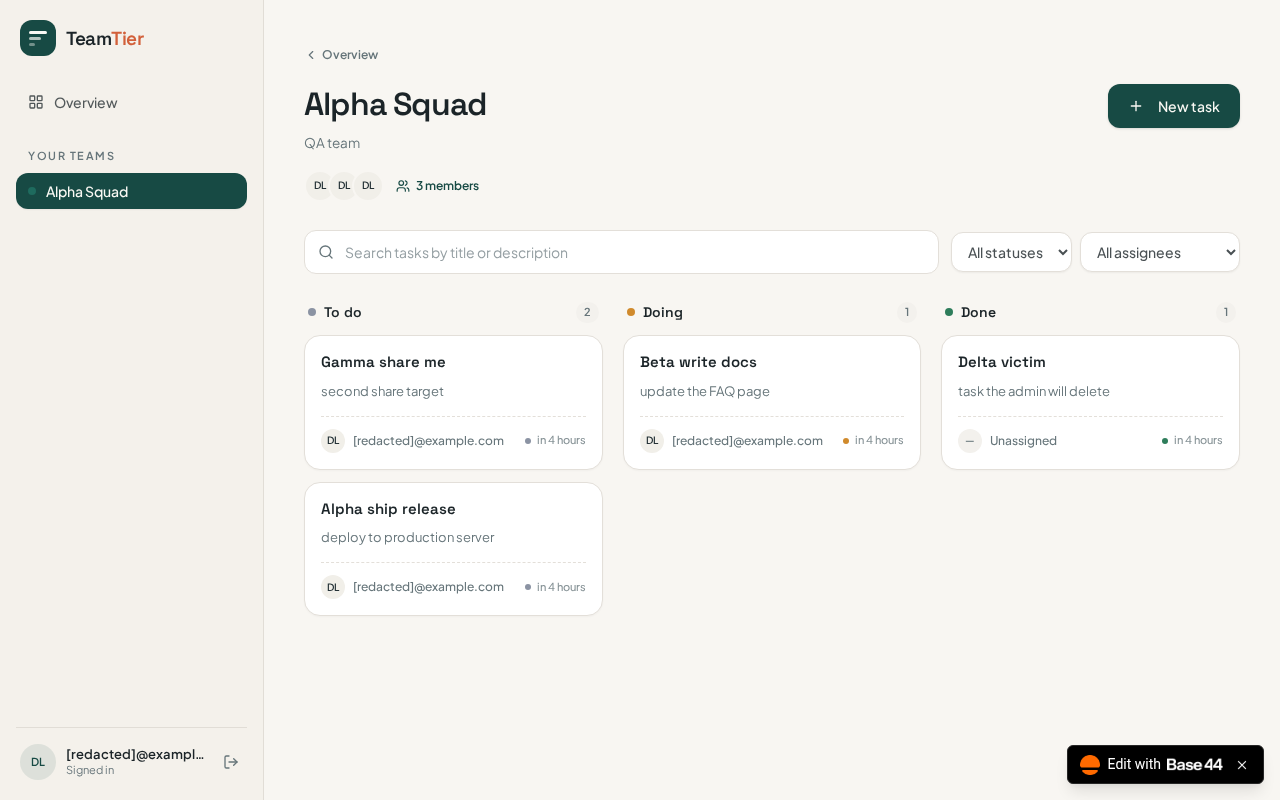
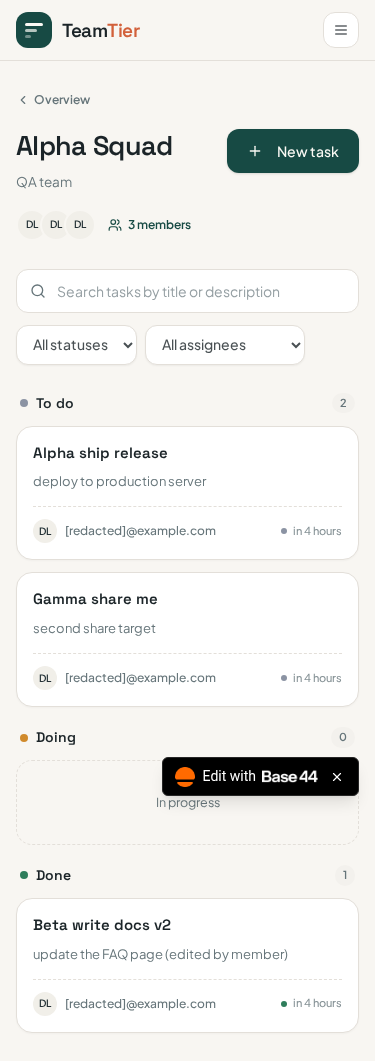
- S3: A Member could make themselves admin by editing their own team-membership record through the app's data API (the request returned 200), after which Delete and the share switch appeared for them. A Member could also add themselves to a task's admins and then delete that task. The plain delete attempt was refused, so F7 passed; the bypass is scored under S3. Single observation
- Not scored: Any signed-in user, even one outside the team, could add a task to any team through the API, and it showed up on that team's board. None of the 22 checks fixed on 16 Oct covers creating tasks in someone else's team, so this doesn't change the score. Single observation
Screenshot to follow
Voided attempt (run 3, 21 Oct 2026 UTC (evening of 20 Oct ET)): First attempt at run 3 voided: tester-side stall before publish, not a Base44 failure. Run 3 was redone on a fresh app on 22 Oct.
The hidden checks (H1–H3)
- H1: Removed member: once the owner removes someone from the team, that person can no longer see or edit the team's tasks, even in a browser where they were already logged in. We checked in the app and by replaying the app's own requests.
- H2: Invite to someone new: inviting an email address that has no account yet works without an error, and that person joins the team after they sign up.
- H3: Share links stay off: a share link that was turned off stays off after sharing is turned on for a different task, and the link can't be guessed from the task's number.
How sure are we? Confidence labels
- Single observation: Seen once: one run, one tool version. Worded "in our run…".
- Repeated result: Seen in 2 or 3 of 3 runs under the same conditions. Worded "in 2 of 3 runs…".
- High-confidence benchmark: A tool's median and tier from 3 consistent runs under the pre-registered plan, with versions recorded and receipts public. No confidence interval, because N is below 5.
Disclosures
- Bolt run 1: the first attempt was voided because of a tester-side interruption, and run 1 was redone from a fresh project. The voided attempt is not scored.
- Bolt doesn't show which model it uses. Its model selector read 'Standard' in all three runs. The run 1 redo (19 Oct 2026, 00:53 UTC) was built while bolt.new showed a 'GLM 5.3 Flash: free this weekend' banner; that offer ended 18 Oct 2026, 11:59pm PT, before runs 2 and 3. We can't confirm the model changed, but conditions may have, so any Bolt finding that splits run 1 from runs 2 and 3 is labelled Single observation.
- v0 is not in v2. Its free credit is a one-time $5 for new sign-ups and $3.81 of it went on our v1 run (16 Oct 2026), so a v2 run would have needed a paid top-up, which v2 does not allow. We decided on 19 Oct 2026 to leave it out. Its v1 result stays up, dated, and is not ranked against the v2 medians.
- No paid top-ups or paid plans. Every run used the free plan with default settings; if free credits ran out, the run stopped and we recorded it.
- Lovable run 3 (21 Oct), Bolt run 2 (22 Oct) and Bolt run 3 (24 Oct) ran out of free credits before the app was deployed. We scored all three as "did not finish on Free": every check fails because there was no app to test, and the 10-point cost penalty applies, so each run scores 0. They are counted in the median, not voided.
- Bolt run 3 (24 Oct) started with 199k of its 300k daily free tokens, because the voided 23 Oct attempt had used about 100K from the same window. It used about 101K before Bolt showed an out-of-tokens wall, about 12 minutes in. Bolt run 2 hit the same wall after a similar amount with a full daily allowance.
- Lovable run 3 started with 5.20 credits, not the 8.20 run 2 had, because an earlier voided attempt on 20 Oct had used the leftover balance. A full daily allowance is 5 credits, and run 2 needed 6.90.
- Run dates are UTC dates (the date of each run's folder in our logs). Most runs started in the evening, US Eastern time, so they show the next day: for example Base44 run 3 (22 Oct UTC) started at 8:20pm ET on 21 Oct. The one exception is the voided first attempt at Bolt run 3, listed under its ET date, 23 Oct (it started 8:13pm ET, which is 24 Oct 00:13 UTC). The Bolt run 3 redo started 24 Oct at 7:12am ET.
- No sponsor or affiliate relationship with Lovable, Bolt or Base44 as of the publish date. No vendor paid for anything on this page. Payment never buys rank.
More: all disclosures · what the evidence labels mean. Spotted a mistake? [email protected]. We check it and correct it publicly, with the date.
Built something with one of these?
Scan my app (free beta) runs a real browser over up to 5 pages of your app: phone layout, safe buttons, junk input, console and network errors. You prove you own the app first, write requests are blocked, and you get a private report with screenshots. It's not a security audit, and it never affects any ranking.
Scan my Lovable appScan my Bolt appScan my Base44 app
Want a deeper check? Our $29 Launch Check runs real-browser checks on your live app (desktop and phone, sign-up as a new user, up to 25 pages) and sends a private report with fix prompts within 48 hours. It's separate from our rankings: your app is never ranked, and payment never changes a tool's score or tier.
FAQ
Which AI app builder did best in the v2 test?
In our v2 test (the same team-app prompt, 3 runs per tool on free plans, 22 checks per run), Base44 came out on top: it built a working team task app in 2 of 3 runs (median 90.67, tier S). Lovable had the best single run (97.5), but one build never opened its team board and one ran out of free credits, so its median is 42.23 (tier C) and unstable. On Bolt's free plan, 2 of 3 runs ran out of tokens before anything deployed (median 0, tier C). No tool earned our High-confidence benchmark label, because none had three consistent runs.
How was the v2 test run?
Same fixed prompt (a team task board with sign-in, invites, Owner/Admin/Member roles, search, filters, read-only share links and per-team data isolation), sent word for word. Free plan, default settings, a fresh project every run, 3 runs per tool on separate days, a 60-minute hard stop, at most 3 fix prompts in a fixed form, no hand-edited code and no paid top-ups. Each run is scored on 22 checks (14 success checks F1–F14, 5 security checks S1–S5, 3 hidden checks H1–H3) plus speed, effort and UX, out of 100. A tool's rank uses its median score. The plan was fixed on 16 Oct 2026, before the first run.
Why isn't v0 in the v2 test?
v0 is not in v2. Its free credit is a one-time $5 for new sign-ups and $3.81 of it went on our v1 run (16 Oct 2026), so a v2 run would have needed a paid top-up, which v2 does not allow. We decided on 19 Oct 2026 to leave it out. Its v1 result stays up, dated, and is not ranked against the v2 medians.
What do Single observation, Repeated result and High-confidence benchmark mean?
Single observation: Seen once: one run, one tool version. Worded "in our run…". Repeated result: Seen in 2 or 3 of 3 runs under the same conditions. Worded "in 2 of 3 runs…". High-confidence benchmark: A tool's median and tier from 3 consistent runs under the pre-registered plan, with versions recorded and receipts public. No confidence interval, because N is below 5.
Did any AI app builder pay for its result?
No sponsor or affiliate relationship with Lovable, Bolt or Base44 as of the publish date. No vendor paid for anything on this page. Payment never buys rank.